Web2026
Kashaf Abi Ja'far
Search thousands of hours of lessons and land on the exact second.
- Live
- Featured
Web2026
Search thousands of hours of lessons and land on the exact second.
In short
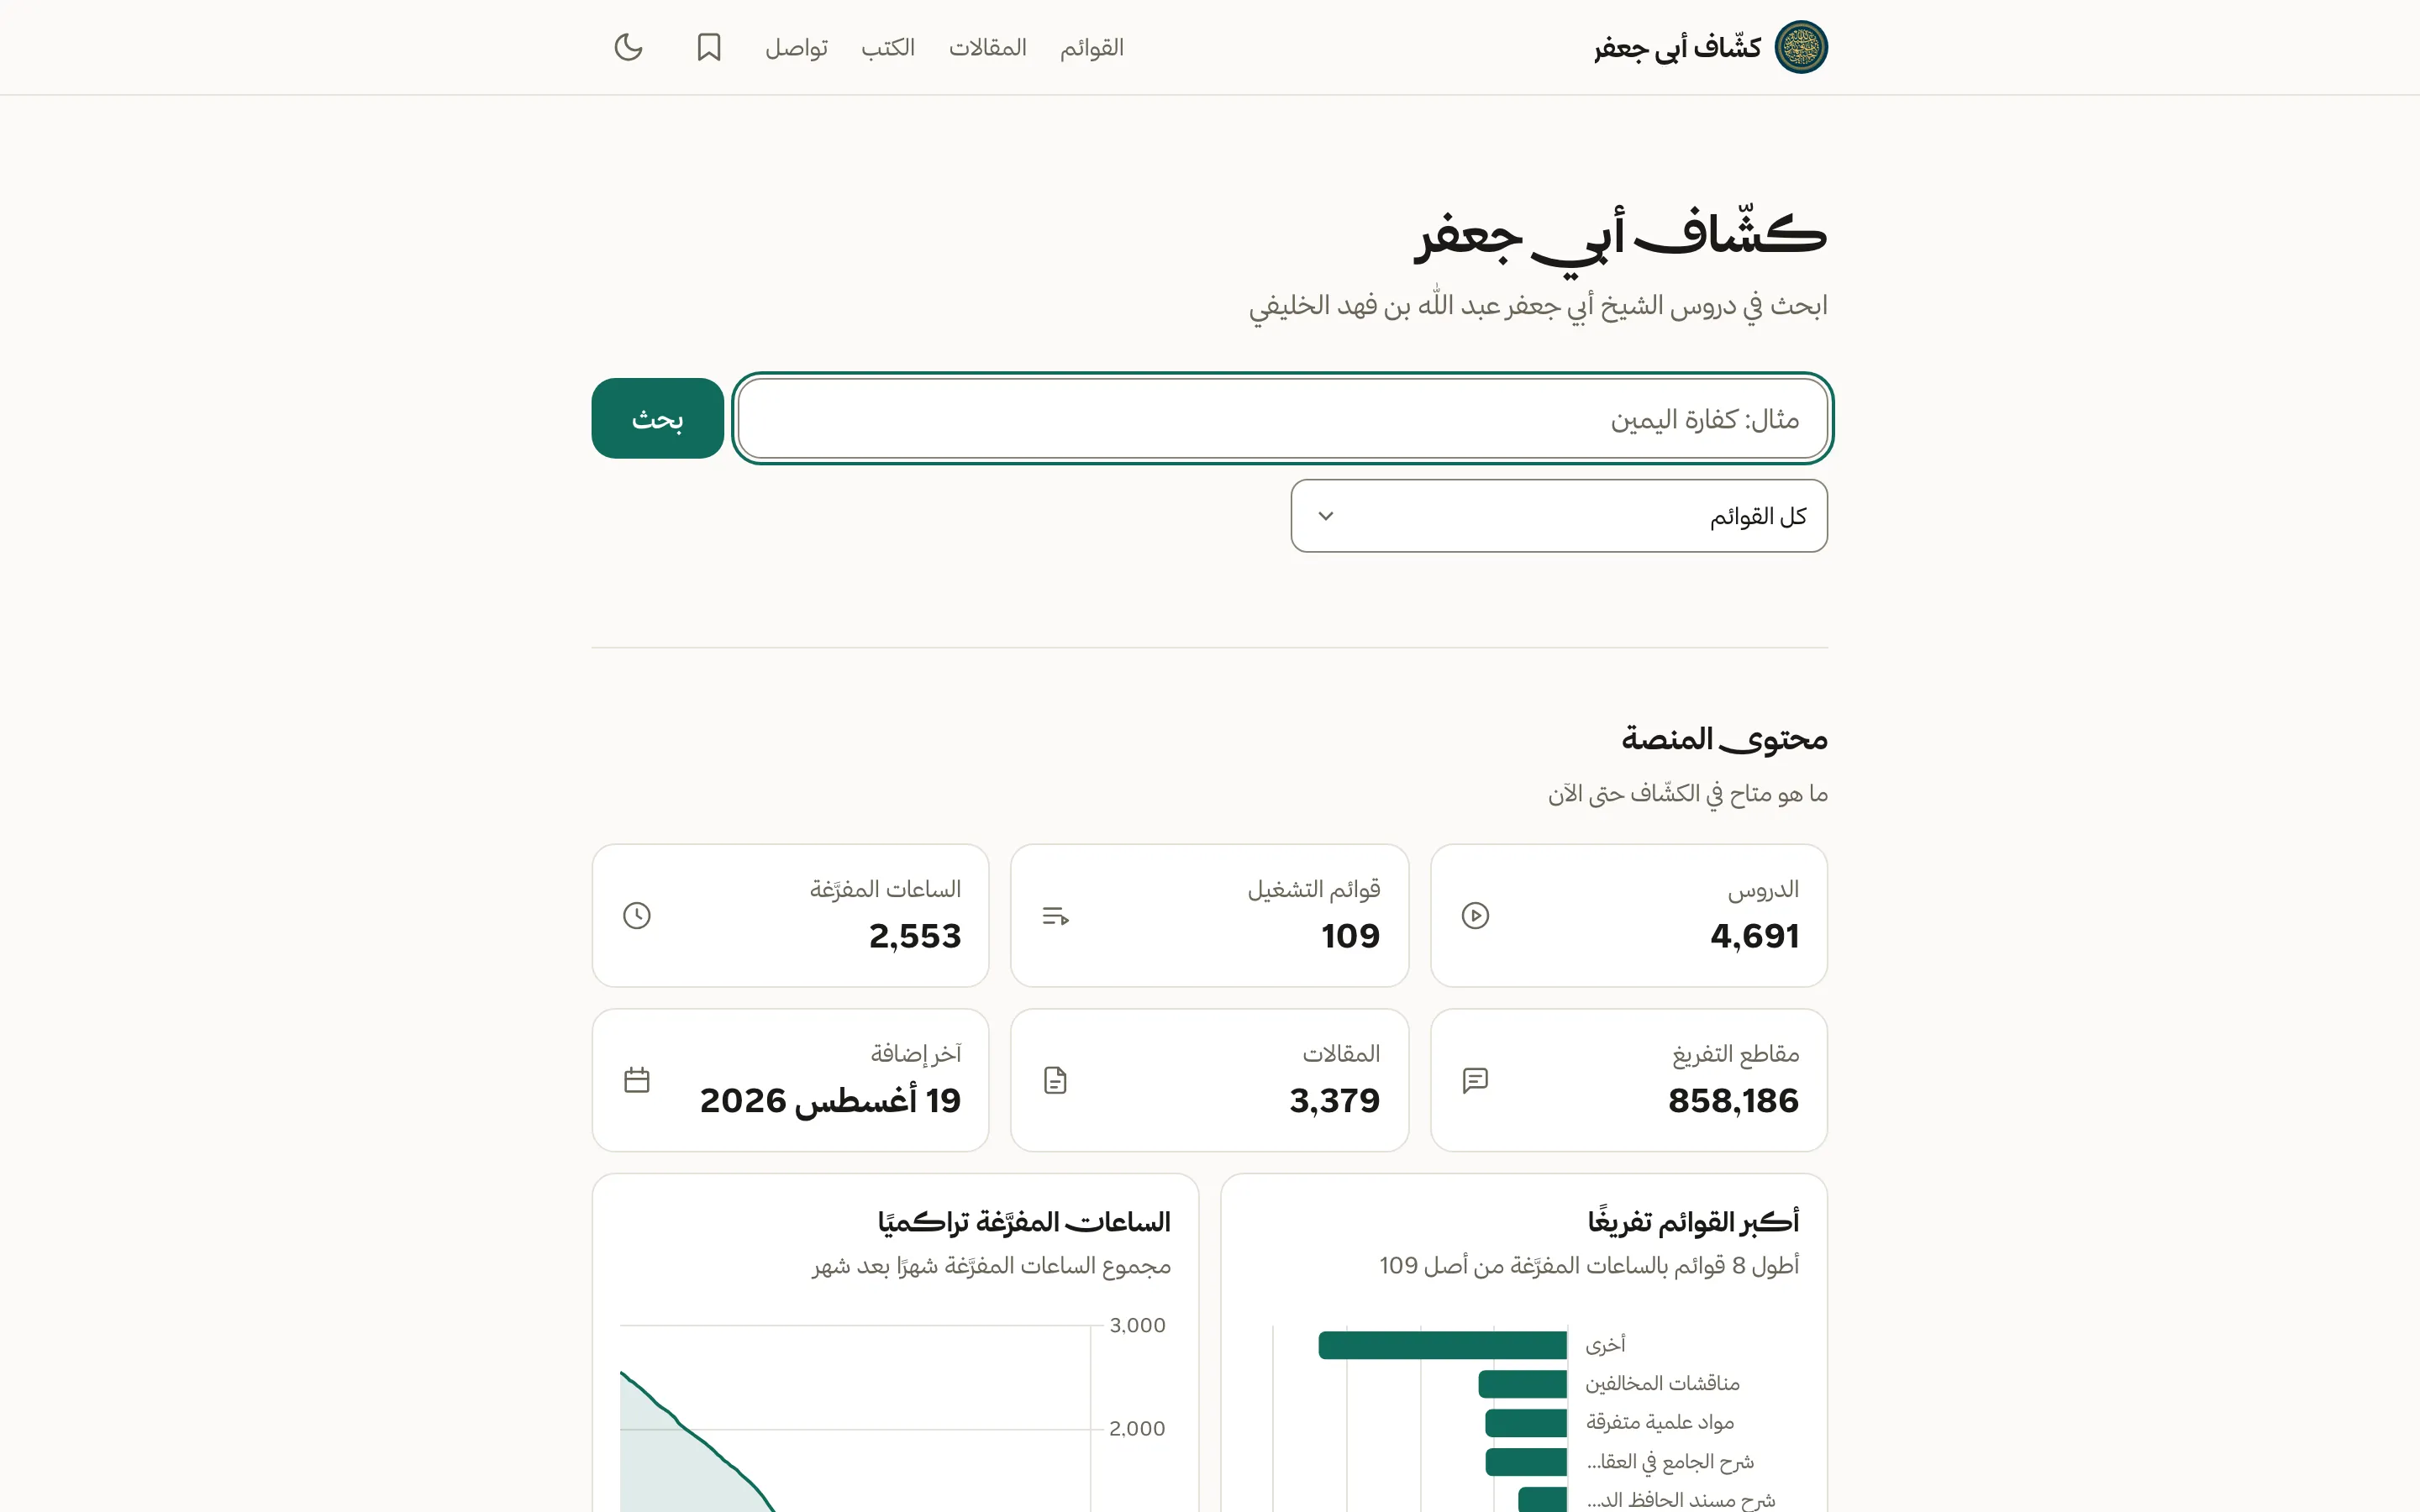
A fully Arabic, right-to-left search engine over a scholar's video lessons and written articles. You type a phrase and get back the passages where it was actually said; one click opens the video at that exact second. No login, no database.
The compartments
Built with
Where to find it
A scholar with years of recorded lessons has, in practice, an unsearchable archive. The knowledge is there, but finding the ten minutes where a specific question was answered means remembering which lesson it was in and scrubbing through it.
This site fixes that. Lessons from the YouTube channel are transcribed automatically, articles are collected from the blog, and everything is indexed in Meilisearch. A search returns transcript segments of roughly thirty seconds each; clicking one opens the player at that timestamp. Beside the player runs an interactive transcript that follows along, can be searched within the lesson, and lets you copy a link to any single line.
There is no backend for search and no database. The index is static and served directly, which is why it stays fast and costs nothing to run.
الشيخ الذي لديه سنوات من الدروس المسجلة يملك عمليًا أرشيفًا غير قابل للبحث. المعرفة موجودة، لكن إيجاد العشر دقائق التي أُجيب فيها عن سؤال بعينه يتطلب تذكّر الدرس ثم التنقّل داخله.
يعالج الموقع ذلك. تُفرَّغ دروس قناة اليوتيوب آليًا، وتُجمَع المقالات من المدوّنة، ويُفهرس الكل في Meilisearch. يعيد البحث مقاطع تفريغ مدة كل منها نحو ثلاثين ثانية؛ والنقر على أحدها يفتح المشغّل عند تلك اللحظة. وبجانب المشغّل تفريغ تفاعلي يتابع تلقائيًا، ويمكن البحث داخله، ونسخ رابط لأي سطر.
لا خادم للبحث ولا قاعدة بيانات. الفهرس ثابت ويُقدَّم مباشرة، ولهذا يبقى سريعًا وبلا كلفة تشغيل.
Results
Each one opens twice: what went wrong on the left, what I did on the right.
01
Problem
Raw transcripts come out as a stream of short caption lines. Indexing each line makes every result a fragment with no context; indexing whole lessons makes every result a two-hour video with no useful timestamp.
What I did
I chunk the transcript into roughly thirty-second passages that keep their start time. That is long enough to read as a thought and short enough that the timestamp is precise. The result is a readable quote that is also a jump target.
02
Problem
The same word appears with and without diacritics, with أ / إ / ا used interchangeably, with ة and ه confused, and with tatweel stretching letters. A visitor searching the phrase they remember hearing rarely types it the way the transcriber wrote it.
What I did
Normalisation runs identically over the index and the query, so both sides are reduced to the same canonical form before matching. Anything else produces a search that works for the person who built it and nobody else.
03
Problem
ASR misreads names, technical terms and classical vocabulary, exactly the words people search for. Presenting a wrong transcript as authoritative text would misrepresent the scholar, which matters far more here than a bad search result.
What I did
The transcript is framed as an index into the audio, not as a quotable source. Every result leads back to the recording at that moment, so the video stays the authority and the text is only the way you find it.
04
Problem
A always-on search backend for a free, non-commercial site is a recurring cost and a thing that can go down at 3am with nobody on call.
What I did
The site is built with Astro and ships a static index that the browser queries directly. Nothing needs to be running for search to work, which is the right operational profile for a project meant to outlive my attention to it.
Next project
pastehtmlDrop an HTML file, get a public URL on its own origin.Open it →افتحه ←Shelf
All projectsAll 40, in six compartments.